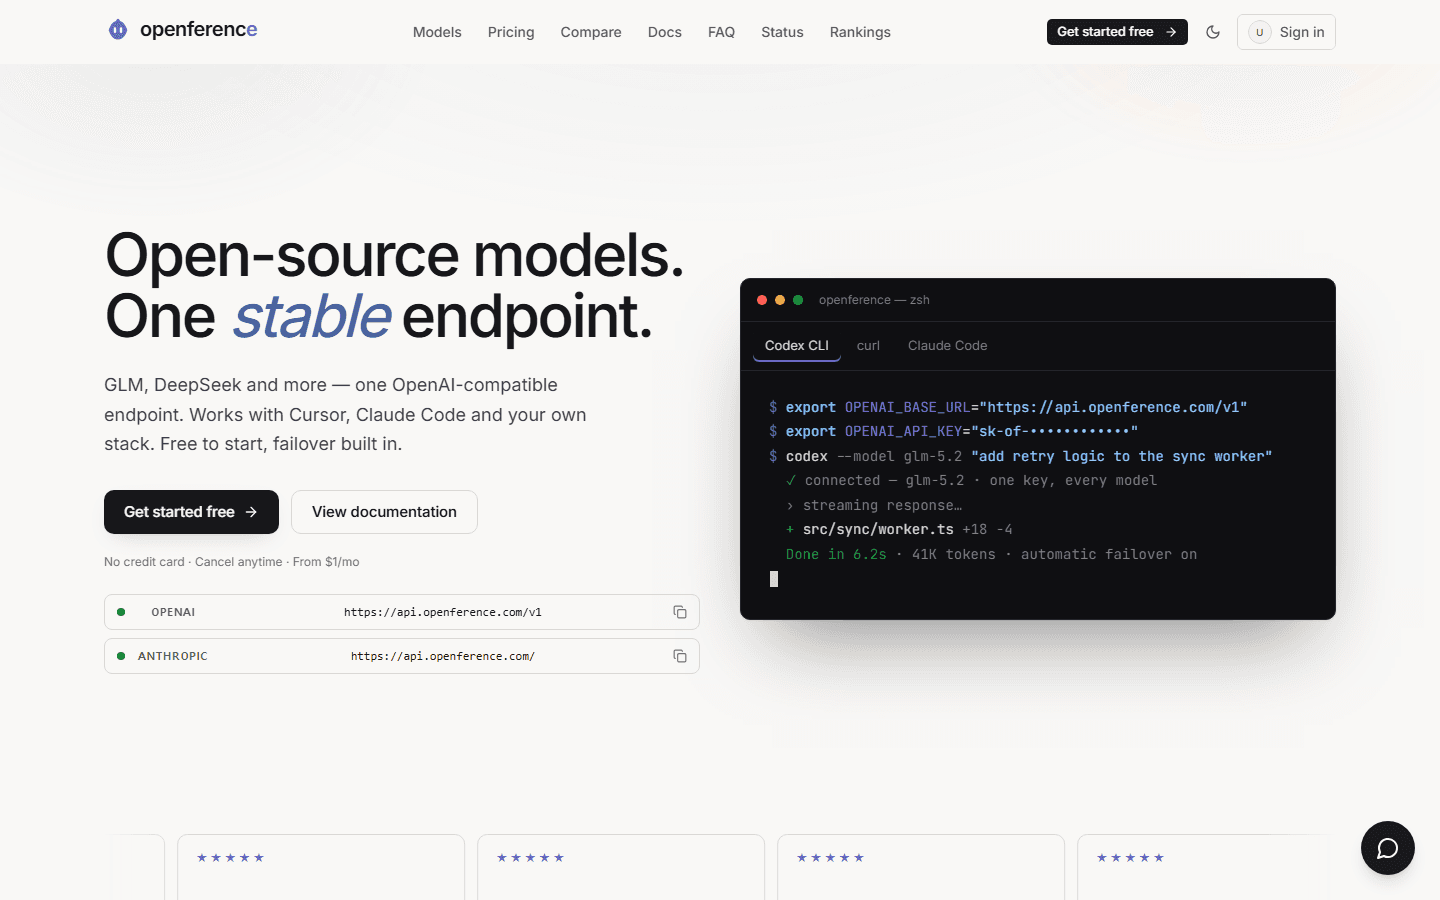
openference.com: the models are real, it is slow, and it keeps cutting out
Verdict
The models are genuine and the decode speed is normal. What is not normal is that a paid request runs for ten minutes and then returns nothing at all. Not recommended.
That is the whole review. The models are real, the decode speed is normal, and the price is not the problem. A request you paid for runs for ten minutes and comes back empty.
Then I measured three models across all three effort levels on the same key. The variable is not the model, it is the default effort. GLM-5.3-Flash produces body text in 5.1 seconds on low and takes 69 seconds on high, where thinking eats 87% of the output. GLM-5.3 on low and high never produces body text at all — 100% thinking, then it hits the length limit.
| Model | effort | First body token | Total | Thinking share | Note |
|---|---|---|---|---|---|
| GLM-5.3-Flash | low | 5.1s | 8.8s | 0% | No thinking at all |
| GLM-5.3-Flash | high | 69s | 77s | 87% | About 9x low |
| GLM-5.3-Flash | max | 86s | 99s | 87% | Same as high |
| GLM-5.3 | low | none | 64s | 100% | Thinking only, then length |
| GLM-5.3 | high | none | 81s | 100% | Same again |
| GLM-5.3 | max | 79s | 83s | 93% | Body starts, then length |
| DeepSeek-V4-Flash | low | 20s | 27s | 75% | Usable |
| DeepSeek-V4-Flash | high | none | 95s | 100% | Thinking spends every token |
| DeepSeek-V4-Flash | max | 27s | 32s | 86% | Close to low this time |
Questions
- Are the models bad?
- No. They are real and the speed is normal — DeepSeek-V4-Flash-0731 answered the same kind of request in 19.7 seconds for 1,468 tokens on the same key. The problem is the service wrapped around them, not the weights.
- So should I pay them?
- Not now. The models are real and the tiers are not badly priced, but a request you paid for has to come back. If that gets fixed, this is worth another look.
More site reviews
Comments
0No comments yet. Be the first, anonymously.